Over the weekend, I explored whether a new AI model that doesn't generate text could improve Maibel’s conversational AI.
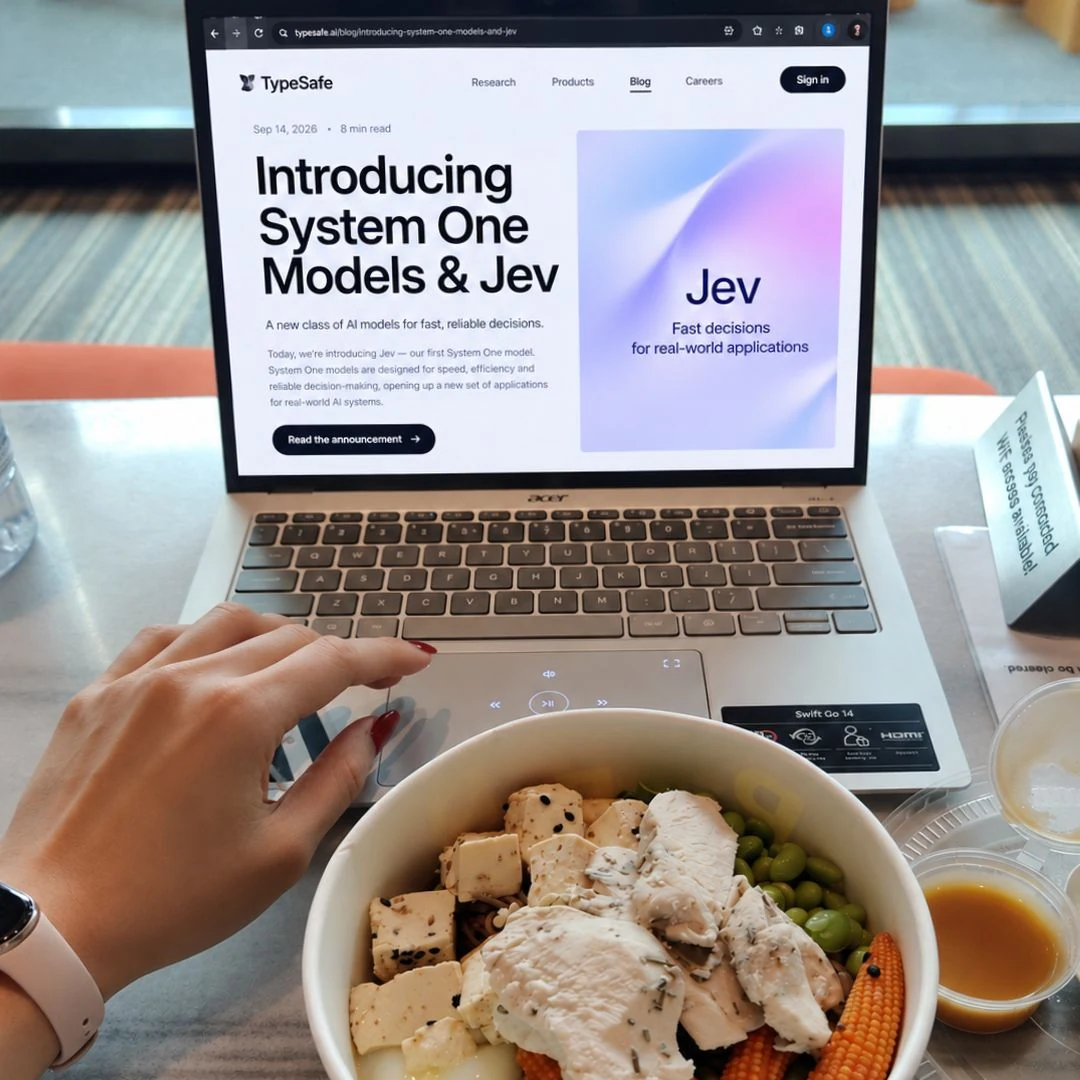
TypeSafe AI just released Jev, its first System One model.
Unlike the generative language models we're familiar with, Jev reads natural language and returns a structured decision: a choice, numerical score or true/false judgment - with probabilities.
Classification itself isn’t new. What excites me is having a model specifically designed for FAST decisions from language, without generating a single word.
Building conversational AI involves far more than generating the final output. I see this every day building Maibel for women's wellness.
Before our companion responds, our system has decisions to make: what does the user mean? Where should this interaction go? Does anything need closer attention?
We already use intent classification. Every additional model call means balancing capability, latency and cost.
The user doesn't see the architecture under the hood. She experiences whether the interaction feels smooth, whether she feels understood, and how responsive our companion is.
So the questions I'm starting with are:
→ Routing: Can it handle parts of our intent classification faster and more efficiently?
→ Proactive decisions: Can it decide whether user outreach is appropriate from defined criteria and personalised context?
→ Evaluations: Can it accurately assess companion responses against our behavioural requirements?
The cost proposition is enticing: TypeSafe lists Jev at $0.042 per million input tokens and reports end-to-end response times of 70-500ms. (Cheap enough to earn a benchmark.)
The next step is to compare Jev against the models we already use for the same classification tasks across accuracy, latency and cost.
I’m also beginning to wonder how many decisions inside an AI-native business actually need a general-purpose LLM at all.
It's why I deliberately designed Maibel to be model-agnostic.
We can't predict what the next frontier model, or an up-and-coming challenger will bring six months from now.
What we can do is build a harness that gives us the ability to test useful capabilities when they appear.
For my team, that means keeping up with what’s changing, identifying where a new capability maps onto a real problem, then running small experiments quickly.
The tooling available now makes those experiments ridiculously fast to build.
Our harness gives us the context, rules, tests and fallbacks to evaluate them without rebuilding Maibel around every new model.
A classifier returning a probability doesn't make our workflow deterministic. Our code still controls what context it receives, what actions are permitted and when further assessment is needed.
That gives us room to test a specialised model for one job without marrying the entire architecture to its provider.
A textless AI classifier was definitely not on my 2026 bingo card.
Designing Maibel so I could test whatever came next was.
Hi, I’m Mabel.
I’m the founder of Maibel. I write about emotional AI, women’s wellness and learning to build the things I wish existed.
More about me